Team project · Emory Computational Linguistics
AuthentiGuard
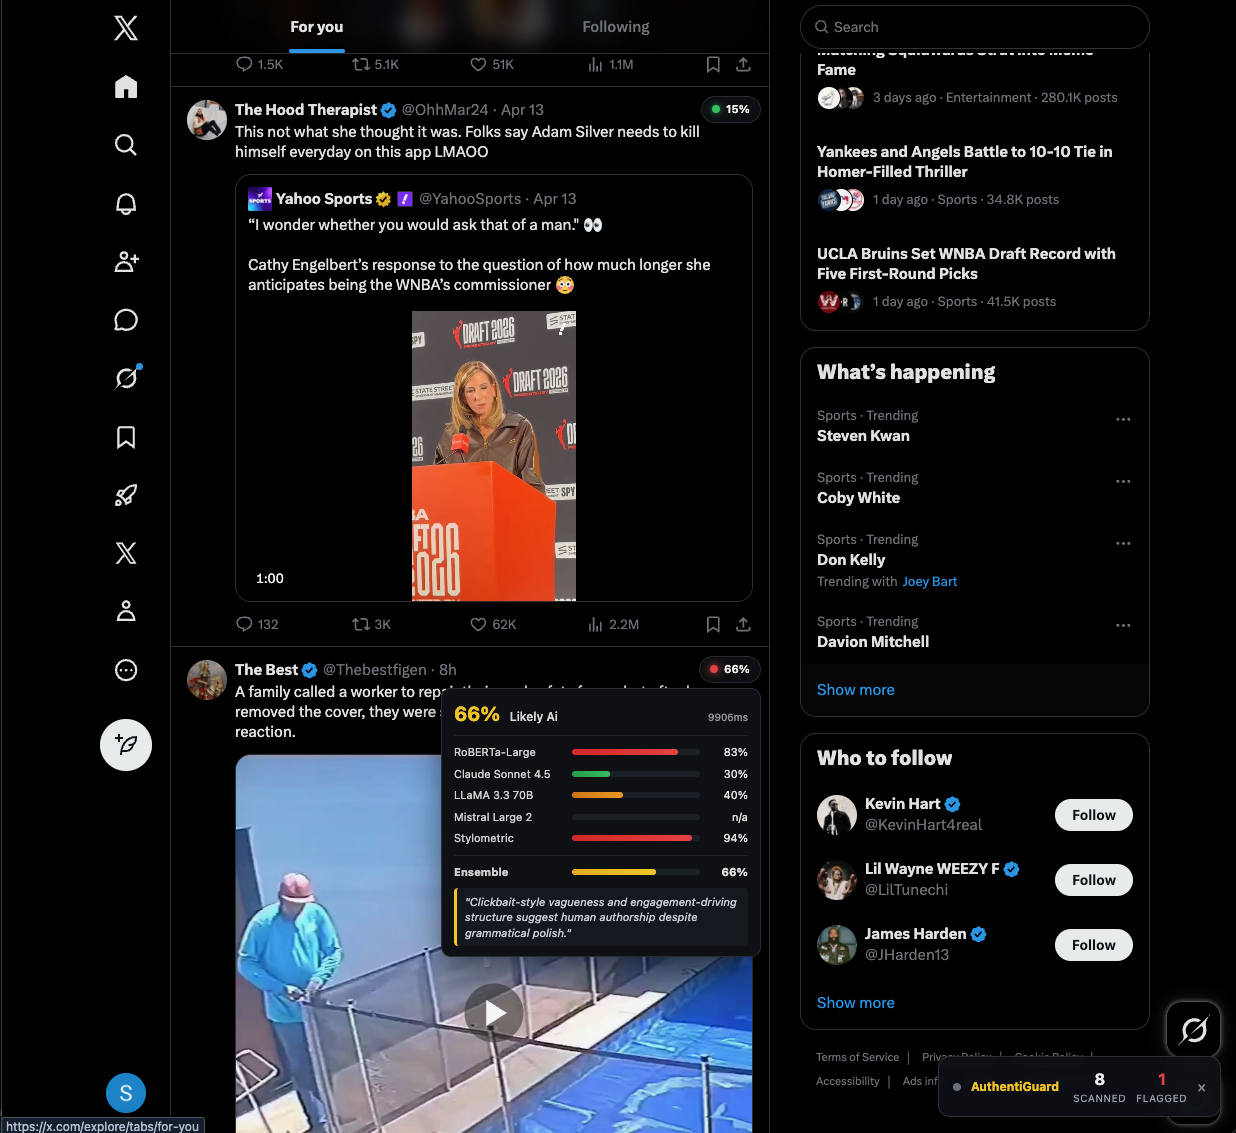
A Chrome extension that checks posts for signs of AI-written text as you browse Twitter/X and Reddit. Open a badge to see how the detectors scored the post, where they disagree, and which responses are unavailable.
The goal
Checking a post with a separate AI-text detector means copying it, opening another site, and pasting it in. We built AuthentiGuard to put that check inside the feed, with a small badge that opens into a breakdown of the results.
I built this with three classmates for Emory’s Computational Linguistics course.
My Part: Backend Integration
I set up the AWS API Gateway and Lambda integration that received POST requests from the browser extension. My work focused on connecting the extension to the backend so posts could be submitted for analysis.
Our approach
The extension watches for new posts with a MutationObserver and sends their text to a FastAPI backend. The backend runs a fine-tuned RoBERTa classifier, three LLM judges, and a stylometric detector that measures patterns in the writing.
The requests run in parallel. The combined score gives 40% weight to RoBERTa, 40% to the LLM judges, and 20% to the stylometric detector. When a detector is unavailable, the remaining weights are adjusted.
Scrolling back through a feed can trigger the same post repeatedly. A cache keyed by the text’s hash avoids running the detectors again for text already processed.
The extension sends post text to the backend hosted on AWS. The LLM judges also use external APIs, so their analysis involves sending that text to model providers.
What we tried
We tried using XGBoost to combine the detector outputs, but it overfit the small dataset. We switched to a fixed weighted vote.
The interface keeps the individual scores visible. In the example above, RoBERTa and the stylometric detector score the post much higher than Claude and LLaMA. A single combined badge would hide that disagreement.
The results
We evaluated the detectors on a balanced 94-example slice of RAID, spanning 11 generator families and eight writing domains. AUROC measures how well a detector ranks AI-written text above human-written text; higher is better.
| Detector | AUROC | False positive rate |
|---|---|---|
| Full ensemble | 0.87 | 14% |
| RoBERTa alone | 0.90 | 0% observed |
RoBERTa alone scored higher on this slice. With only 94 examples, the difference is too small a basis for a broad claim about which approach works better.
The ensemble’s 14% false positive rate means some human-written examples were classified as AI-written at the evaluation threshold. That matters for a feed tool: a score can be mistaken for proof about an author. Testing the badge thresholds on short social posts is the next evaluation step.
The benchmark results describe this small RAID slice; accuracy on short social posts still needs its own evaluation.
Next Steps
I’d test on labeled short social posts and measure false positives at different badge thresholds. I’d also verify separation between the classifier’s training data and evaluation examples, and assess the ensemble weights on separate validation data.
For everyday browsing, I’d measure API cost, latency, and rate-limit behavior over a scrolling session. The example above took about ten seconds.